

Get instant access to Professional-Machine-Learning-Engineer Practice Tests 2021 Free Updated Today!
Welcome to download the newest PassLeader Professional-Machine-Learning-Engineer PDF dumps ( 72 Q&As)
NEW QUESTION 39
You have deployed multiple versions of an image classification model on Al Platform. You want to monitor the performance of the model versions overtime. How should you perform this comparison?
- A. Compare the mean average precision across the models using the Continuous Evaluation feature
- B. Compare the receiver operating characteristic (ROC) curve for each model using the What-lf Tool
- C. Compare the loss performance for each model on the validation data
- D. Compare the loss performance for each model on a held-out dataset.
Answer: C
NEW QUESTION 40
A Machine Learning Specialist deployed a model that provides product recommendations on a company's website. Initially, the model was performing very well and resulted in customers buying more products on average. However, within the past few months, the Specialist has noticed that the effect of product recommendations has diminished and customers are starting to return to their original habits of spending less.
The Specialist is unsure of what happened, as the model has not changed from its initial deployment over a year ago.
Which method should the Specialist try to improve model performance?
- A. The model needs to be completely re-engineered because it is unable to handle product inventory changes.
- B. The model should be periodically retrained from scratch using the original data while adding a regularization term to handle product inventory changes
- C. The model's hyperparameters should be periodically updated to prevent drift.
- D. The model should be periodically retrained using the original training data plus new data as product inventory changes.
Answer: D
NEW QUESTION 41
You started working on a classification problem with time series data and achieved an area under the receiver operating characteristic curve (AUC ROC) value of 99% for training data after just a few experiments. You haven't explored using any sophisticated algorithms or spent any time on hyperparameter tuning. What should your next step be to identify and fix the problem?
- A. Address the model overfitting by using a less complex algorithm.
- B. Address data leakage by removing features highly correlated with the target value.
- C. Address data leakage by applying nested cross-validation during model training.
- D. Address the model overfitting by tuning the hyperparameters to reduce the AUC ROC value.
Answer: C
NEW QUESTION 42
You are building a real-time prediction engine that streams files which may contain Personally Identifiable Information (Pll) to Google Cloud. You want to use the Cloud Data Loss Prevention (DLP) API to scan the files. How should you ensure that the Pll is not accessible by unauthorized individuals?
- A. Create two buckets of data Sensitive and Non-sensitive Write all data to the Non-sensitive bucket Periodically conduct a bulk scan of that bucket using the DLP API, and move the sensitive data to the Sensitive bucket
- B. Stream all files to Google CloudT and then write the data to BigQuery Periodically conduct a bulk scan of the table using the DLP API.
- C. Create three buckets of data: Quarantine, Sensitive, and Non-sensitive Write all data to the Quarantine bucket.
- D. Stream all files to Google Cloud, and write batches of the data to BigQuery While the data is being written to BigQuery conduct a bulk scan of the data using the DLP API.
- E. Periodically conduct a bulk scan of that bucket using the DLP API, and move the data to either the Sensitive or Non-Sensitive bucket
Answer: B
NEW QUESTION 43
A financial services company is building a robust serverless data lake on Amazon S3. The data lake should be flexible and meet the following requirements:
* Support querying old and new data on Amazon S3 through Amazon Athena and Amazon Redshift Spectrum.
* Support event-driven ETL pipelines
* Provide a quick and easy way to understand metadata
Which approach meets these requirements?
- A. Use an AWS Glue crawler to crawl S3 data, an AWS Lambda function to trigger an AWS Glue ETL job, and an AWS Glue Data catalog to search and discover metadata.
- B. Use an AWS Glue crawler to crawl S3 data, an AWS Lambda function to trigger an AWS Batch job, and an external Apache Hive metastore to search and discover metadata.
- C. Use an AWS Glue crawler to crawl S3 data, an Amazon CloudWatch alarm to trigger an AWS Glue ETL job, and an external Apache Hive metastore to search and discover metadata.
- D. Use an AWS Glue crawler to crawl S3 data, an Amazon CloudWatch alarm to trigger an AWS Batch job, and an AWS Glue Data Catalog to search and discover metadata.
Answer: A
NEW QUESTION 44
A data scientist wants to use Amazon Forecast to build a forecasting model for inventory demand for a retail company. The company has provided a dataset of historic inventory demand for its products as a .csv file stored in an Amazon S3 bucket. The table below shows a sample of the dataset.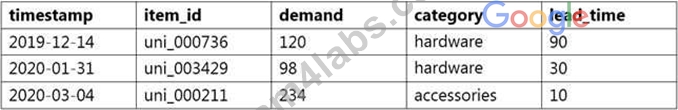
How should the data scientist transform the data?
- A. Use a Jupyter notebook in Amazon SageMaker to transform the data into the optimized protobuf recordIO format. Upload the dataset in this format to Amazon S3.
- B. Use a Jupyter notebook in Amazon SageMaker to separate the dataset into a related time series dataset and an item metadata dataset. Upload both datasets as tables in Amazon Aurora.
- C. Use ETL jobs in AWS Glue to separate the dataset into a target time series dataset and an item metadata dataset. Upload both datasets as .csv files to Amazon S3.
- D. Use AWS Batch jobs to separate the dataset into a target time series dataset, a related time series dataset, and an item metadata dataset. Upload them directly to Forecast from a local machine.
Answer: B
NEW QUESTION 45
You are developing a Kubeflow pipeline on Google Kubernetes Engine. The first step in the pipeline is to issue a query against BigQuery. You plan to use the results of that query as the input to the next step in your pipeline. You want to achieve this in the easiest way possible. What should you do?
- A. Write a Python script that uses the BigQuery API to execute queries against BigQuery Execute this script as the first step in your Kubeflow pipeline
- B. Use the BigQuery console to execute your query and then save the query results Into a new BigQuery table.
- C. Locate the Kubeflow Pipelines repository on GitHub Find the BigQuery Query Component, copy that component's URL, and use it to load the component into your pipeline. Use the component to execute queries against BigQuery
- D. Use the Kubeflow Pipelines domain-specific language to create a custom component that uses the Python BigQuery client library to execute queries
Answer: B
NEW QUESTION 46
You work for a global footwear retailer and need to predict when an item will be out of stock based on historical inventory dat a. Customer behavior is highly dynamic since footwear demand is influenced by many different factors. You want to serve models that are trained on all available data, but track your performance on specific subsets of data before pushing to production. What is the most streamlined and reliable way to perform this validation?
- A. Use the last relevant week of data as a validation set to ensure that your model is performing accurately on current data
- B. Use k-fold cross-validation as a validation strategy to ensure that your model is ready for production.
- C. Use the entire dataset and treat the area under the receiver operating characteristics curve (AUC ROC) as the main metric.
- D. Use the TFX ModelValidator tools to specify performance metrics for production readiness
Answer: D
NEW QUESTION 47
You are an ML engineer at a regulated insurance company. You are asked to develop an insurance approval model that accepts or rejects insurance applications from potential customers. What factors should you consider before building the model?
- A. Redaction, reproducibility, and explainability
- B. Federated learning, reproducibility, and explainability
- C. Differential privacy federated learning, and explainability
- D. Traceability, reproducibility, and explainability
Answer: A
NEW QUESTION 48
A company ingests machine learning (ML) data from web advertising clicks into an Amazon S3 data lake. Click data is added to an Amazon Kinesis data stream by using the Kinesis Producer Library (KPL). The data is loaded into the S3 data lake from the data stream by using an Amazon Kinesis Data Firehose delivery stream.
As the data volume increases, an ML specialist notices that the rate of data ingested into Amazon S3 is relatively constant. There also is an increasing backlog of data for Kinesis Data Streams and Kinesis Data Firehose to ingest.
Which next step is MOST likely to improve the data ingestion rate into Amazon S3?
- A. Decrease the retention period for the data stream.
- B. Increase the number of shards for the data stream.
- C. Increase the number of S3 prefixes for the delivery stream to write to.
- D. Add more consumers using the Kinesis Client Library (KCL).
Answer: B
Explanation:
Explanation/Reference:
NEW QUESTION 49
A Machine Learning Specialist wants to bring a custom algorithm to Amazon SageMaker. The Specialist implements the algorithm in a Docker container supported by Amazon SageMaker.
How should the Specialist package the Docker container so that Amazon SageMaker can launch the training correctly?
- A. Configure the training program as an ENTRYPOINTnamed train
- B. Use CMD configin the Dockerfile to add the training program as a CMD of the image
- C. Modify the bash_profile file in the container and add a bashcommand to start the training program
- D. Copy the training program to directory /opt/ml/train
Answer: B
NEW QUESTION 50
You are designing an ML recommendation model for shoppers on your company's ecommerce website. You will use Recommendations Al to build, test, and deploy your system. How should you develop recommendations that increase revenue while following best practices?
- A. Import your user events and then your product catalog to make sure you have the highest quality event stream
- B. Because it will take time to collect and record product data, use placeholder values for the product catalog to test the viability of the model.
- C. Use the "Other Products You May Like" recommendation type to increase the click-through rate
- D. Use the "Frequently Bought Together' recommendation type to increase the shopping cart size for each order.
Answer: A
NEW QUESTION 51
A Machine Learning Specialist is building a model that will perform time series forecasting using Amazon SageMaker. The Specialist has finished training the model and is now planning to perform load testing on the endpoint so they can configure Auto Scaling for the model variant.
Which approach will allow the Specialist to review the latency, memory utilization, and CPU utilization during the load test?
- A. Generate an Amazon CloudWatch dashboard to create a single view for the latency, memory utilization, and CPU utilization metrics that are outputted by Amazon SageMaker.
- B. Build custom Amazon CloudWatch Logs and then leverage Amazon ES and Kibana to query and visualize the log data as it is generated by Amazon SageMaker.
- C. Send Amazon CloudWatch Logs that were generated by Amazon SageMaker to Amazon ES and use Kibana to query and visualize the log data.
- D. Review SageMaker logs that have been written to Amazon S3 by leveraging Amazon Athena and Amazon QuickSight to visualize logs as they are being produced.
Answer: A
Explanation:
Explanation/Reference: https://docs.aws.amazon.com/sagemaker/latest/dg/monitoring-cloudwatch.html
NEW QUESTION 52
You have been asked to develop an input pipeline for an ML training model that processes images from disparate sources at a low latency. You discover that your input data does not fit in memory. How should you create a dataset following Google-recommended best practices?
- A. Convert the images Into TFRecords, store the images in Cloud Storage, and then use the tf. data API to read the images for training
- B. Convert the images to tf .Tensor Objects, and then run tf. data. Dataset. from_tensors ().
- C. Create a tf.data.Dataset.prefetch transformation
- D. Convert the images to tf .Tensor Objects, and then run Dataset. from_tensor_slices{).
Answer: A
NEW QUESTION 53
You have a functioning end-to-end ML pipeline that involves tuning the hyperparameters of your ML model using Al Platform, and then using the best-tuned parameters for training. Hypertuning is taking longer than expected and is delaying the downstream processes. You want to speed up the tuning job without significantly compromising its effectiveness. Which actions should you take?
Choose 2 answers
- A. Change the search algorithm from Bayesian search to random search.
- B. Decrease the number of parallel trials
- C. Set the early stopping parameter to TRUE
- D. Decrease the range of floating-point values
- E. Decrease the maximum number of trials during subsequent training phases.
Answer: A,E
NEW QUESTION 54
You are an ML engineer at a regulated insurance company. You are asked to develop an insurance approval model that accepts or rejects insurance applications from potential customers. What factors should you consider before building the model?
- A. Traceability, reproducibility, and explainability
- B. Federated learning, reproducibility, and explainability
- C. Redaction, reproducibility, and explainability
- D. Differential privacy federated learning, and explainability
Answer: A
NEW QUESTION 55
A Machine Learning Specialist receives customer data for an online shopping website. The data includes demographics, past visits, and locality information. The Specialist must develop a machine learning approach to identify the customer shopping patterns, preferences, and trends to enhance the website for better service and smart recommendations.
Which solution should the Specialist recommend?
- A. Random Cut Forest (RCF) over random subsamples to identify patterns in the customer database.
- B. A neural network with a minimum of three layers and random initial weights to identify patterns in the customer database.
- C. Latent Dirichlet Allocation (LDA) for the given collection of discrete data to identify patterns in the customer database.
- D. Collaborative filtering based on user interactions and correlations to identify patterns in the customer database.
Answer: D
Explanation:
Explanation
NEW QUESTION 56
You work on a growing team of more than 50 data scientists who all use AI Platform. You are designing a strategy to organize your jobs, models, and versions in a clean and scalable way. Which strategy should you choose?
- A. Set up a BigQuery sink for Cloud Logging logs that is appropriately filtered to capture information about AI Platform resource usage. In BigQuery, create a SQL view that maps users to the resources they are using
- B. Separate each data scientist's work into a different project to ensure that the jobs, models, and versions created by each data scientist are accessible only to that user.
- C. Set up restrictive IAM permissions on the AI Platform notebooks so that only a single user or group can access a given instance.
- D. Use labels to organize resources into descriptive categories. Apply a label to each created resource so that users can filter the results by label when viewing or monitoring the resources.
Answer: C
NEW QUESTION 57
A Machine Learning Specialist wants to determine the appropriate
SageMakerVariantInvocationsPerInstancesetting for an endpoint automatic scaling configuration.
The Specialist has performed a load test on a single instance and determined that peak requests per second (RPS) without service degradation is about 20 RPS. As this is the first deployment, the Specialist intends to set the invocation safety factor to 0.5.
Based on the stated parameters and given that the invocations per instance setting is measured on a per- minute basis, what should the Specialist set as the SageMakerVariantInvocationsPerInstance setting?
- A. 0
- B. 1
- C. 2
- D. 2,400
Answer: A
NEW QUESTION 58
......
Sep-2021 Latest Exam4Labs Professional-Machine-Learning-Engineer Exam Dumps with PDF and Exam Engine: https://www.exam4labs.com/Professional-Machine-Learning-Engineer-practice-torrent.html
Premium Quality Google Professional-Machine-Learning-Engineer Online dumps: https://drive.google.com/open?id=1JfKQEuTxexTcyK5vHqFTCyGoUSdWuu5N